📄 Upgraded! Thai document AI, two free models
Version 2.1 released 18 November 2026 · version 2.0 announced 12 November 2026
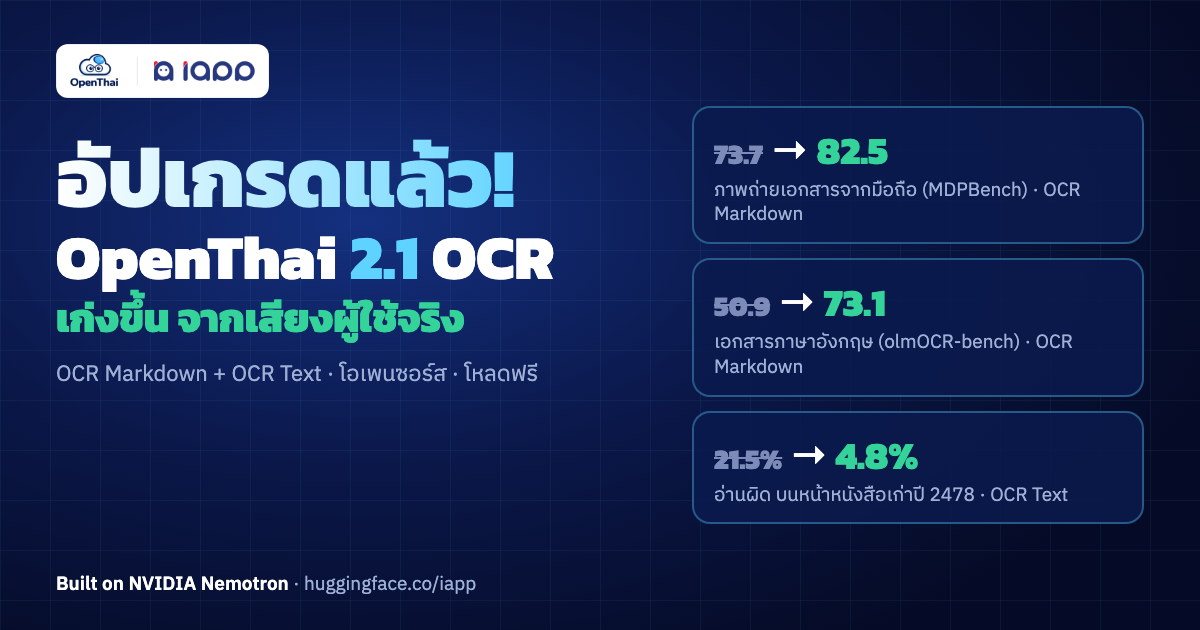
OCR Markdown 0.63BOCR Text 6.6 MBCommercial use allowedThai + Englishv2.1
Sound familiar? You scan a stack of government documents, or take a photo of one with your phone, and you want the text. But the OCR turns every table into one long line, you can't tell which number belongs to which row, and you end up typing it all in again.
The OpenThai team at iApp Technology gives away two Thai OCR models, free to download and free for commercial use. Version 2.1 reads phone photos of documents much better and fixes what users reported after the 2.0 launch (what's new in 2.1).
| OpenThai 2.1 OCR Markdown | OpenThai 2.1 OCR Text | |
|---|---|---|
| What it does | Page or phone photo → Markdown, tables as HTML (merged cells supported), formulas as LaTeX, with a box and a class for every block | Page → text in reading order, with a box and a confidence for every line |
| Size | 0.63B parameters | 1.60M parameters, ONNX files 6.6 MB in all (detector 1.8 MB, recognizer 2.4 MB, and a second 2.4 MB recognizer for loopless fonts) |
| Runs on | One NVIDIA GPU with vLLM, or a Mac or CPU with llama.cpp (GGUF) | CPU only, no GPU needed |
| Speed | 1.5 s per page on an H100; about 6 s per page on an Apple M3 Max (GGUF) | 0.39 s per page, about 950 pages a minute on 8 cores |
| Built on | NVIDIA Nemotron 3.5 Parse | PaddlePaddle PP-OCRv6-tiny |
| Licence | OpenMDW-1.1 | Apache-2.0 |
| Good for | Documents with tables, phone photos, papers and slides, preparing data for RAG | Large volumes of plain text, machines without a GPU, confidential documents that cannot leave the building |
1) OpenThai 2.1 OCR Markdown: tables stay tables, and phone photos read
It reads Thai and English document pages into Markdown, with tables as HTML including rowspan and colspan. It is a full fine-tune of NVIDIA Nemotron 3.5 Parse (0.63B), so it keeps Parse's layout boxes, block classes and reading order, and works with Parse's serving stack anywhere.
New in 2.1
- Phone photos of documents, bent, creased or shadowed: MDPBench (Thai and English, mostly photos) up from 73.7 to 82.5; Thai only, from 72.7 to 80.7.
- Nine more kinds of page: academic papers, books, comics, exams, magazines, newspapers, reports, slides and textbooks, in Thai and English. English PDFs (olmOCR-bench) up from 50.9 to 73.1; OmniDocBench v1.6 from 61.8 to 79.6.
- Formulas come out as LaTeX. Page headers and footers stay out of the Markdown, blank pages no longer get invented text, and ำ is written as one character.
- Thai government tables are as good as before: 94.0 on th-docs-tables v1 (2.0: 95.2, not a significant difference), against 91.6 for Typhoon OCR V2 2B.
- The same size and speed: 1.5 s per page on one NVIDIA H100.
- New: GGUF files for llama.cpp. Run it on a Mac or a CPU without vLLM, at about 6 s per page on an Apple M3 Max (Metal). Its Markdown matched the original model's on all 30 test pages.
| Model | th-docs-tables v1 (65 pages) | ThaiOCRBench tables (193 images) | Thai text, printed (12 sets) | MDPBench TH+EN (320 pages) | MDPBench Thai | olmOCR-bench | OmniDocBench v1.6 | Seconds per page |
|---|---|---|---|---|---|---|---|---|
| OpenThai2.1-OCR-Markdown | 94.0 | 69.5 | 90.2 | 82.5 | 80.7 | 73.1 | 79.6 | 1.5 |
| OpenThai2.0-OCR-Markdown | 95.2 | 68.9 | 90.3 | 73.7 | 72.7 | 50.9 | 61.8 | 1.5 |
| Nemotron 3.5 Parse (base) | 91.3 | 68.3 | 89.0 | 79.6 | 77.4 | 62.4 | 80.1 | 1.8 |
| Typhoon OCR V2 2B | 91.6 | 67.6 | 89.6 | 87.0 | 85.0 | 84.7 | 91.5 | 1.0 |
Bold is the best in each column (for seconds per page, the fastest). Against Typhoon OCR V2 2B, with paired 95% intervals: ahead on th-docs-tables by +2.3 [+0.4, +4.8]; no significant difference on ThaiOCRBench tables or Thai text; behind on MDPBench by 4.5 [−7.0, −2.0], most on photos and on tables in photos; behind by about 12 points on olmOCR-bench and OmniDocBench, most on formulas. MDPBench is scored without the formula metric (CDM). The new Royal Gazette pages on the 2.0 page were not re-measured for 2.1. Every detail is on the model card.
How to use it
Serve it with vLLM exactly as the base model, then parse pages with NVIDIA's DocumentParser from the nemotron_parse package that ships with the model (box-and-class mode, one pass). vLLM runs on Linux; on Windows, use WSL2.
hf download iapp/OpenThai2.1-OCR-Markdown-20261118 --local-dir OpenThai2.1-OCR-Markdown
pip install -e "./OpenThai2.1-OCR-Markdown[vllm,client]"
vllm serve ./OpenThai2.1-OCR-Markdown --served-model-name nemotron-parse --trust-remote-code
from nemotron_parse.inference import DocumentParser, GenerationError

with DocumentParser(base_url="http://localhost:8000/v1", model="nemotron-parse") as parser:
    doc = parser.parse("page.png", mode="single")
    print(doc["markdown"])  # Markdown; tables as HTML with rowspan/colspan; formulas as $$...$$
- Want 2.0's output? (page headers and footers kept in the Markdown, formulas as
\(...\)) Set it withPostprocessOptions; see the model card. - On a Mac or a CPU: use the GGUF files with our llama.cpp fork (iapp-technology/llama.cpp, branch
nemotron-parse). Upstream llama.cpp does not include this architecture. - Step-by-step guide for Windows, Mac and Linux, with a script for pictures and PDFs: on the iApp blog. It was written for 2.0 and works for 2.1; just change the model name.
2) OpenThai 2.1 OCR Text: a tiny 6.6 MB model, no GPU
A Thai and English printed-text OCR that runs on an ordinary CPU: a PP-OCRv6-tiny line detector (1.8 MB) and a Thai line recognizer trained by iApp (2.4 MB), on OpenVINO or ONNX Runtime. It is the engine behind iApp Document OCR.
New in 2.1 (2.0's model files with a new runtime, and a second recognizer for loopless fonts)
- Old books with floating tone marks keep their marks: on a test page from a 1935 book that a user sent in, the error rate fell from 21.5% to 4.8% (one page, not a benchmark).
- Loopless fonts (Kanit, Prompt, Sukhumvit Set) are no longer read as Latin letters.
- Two- and three-column pages are read column by column; lists and tables are still read row by row.
- A lone digit or letter in a table cell is kept, and amounts written with a decimal comma, such as "280,00", come out as "280.00".
- Less memory on Mac and Windows.
- The 12-set printed average is up from 87.8 to 88.3, and ThaiOCRBench full pages from 82.0 to 84.1.
- The same speed: 0.39 s per page, offline, so confidential documents stay on the machine.
Most of these fixes came from real users: comments on Facebook and projects on GitHub built on the model. Thank you.
Every engine read the same pages and was scored the same way. The score is character accuracy, 100 × (1 − CER); higher is better.
| Engine | Average, 12 printed sets | Court judgments | Royal Gazette | Budget | Old books | ThaiOCRBench | Handwriting |
|---|---|---|---|---|---|---|---|
| OpenThai2.1-OCR-Text (v2.1.1, CPU) | 88.2 | 97.0 | 96.3 | 99.6 | 78.8 | 83.8 | 10.3 |
| OpenThai2.0-OCR-Text (v2.0.0, CPU) | 87.8 | 97.0 | 96.3 | 99.5 | 77.1 | 82.0 | 10.3 |
| OpenThai2.0-OCR-Markdown (GPU) | 90.3 | 96.2 | 98.0 | 98.2 | 79.7 | 90.6 | 78.9 |
| Typhoon OCR V2 2B | 89.6 | 96.2 | 94.6 | 97.3 | 77.2 | 87.3 | 76.7 |
| NVIDIA Nemotron 3.5 Parse | 89.0 | 96.9 | 92.2 | 98.9 | 76.9 | 92.0 | 57.3 |
| Typhoon OCR 1.5 2B | 87.5 | 92.4 | 92.5 | 97.2 | 78.6 | 71.4 | 94.5 |
| Gemini 2.5 Flash | 87.1 | 94.7 | 92.6 | 81.0 | 77.9 | 88.8 | 86.7 |
| dots.mocr | 86.4 | 96.3 | 93.1 | 99.5 | 76.3 | 78.8 | 39.4 |
| OneOCR (Microsoft, Windows) | 85.0 | 95.1 | 96.6 | 99.8 | 78.6 | 81.8 | 91.0 |
| Google Cloud Vision | 83.6 | 93.9 | 87.8 | 75.0 | 73.6 | 85.6 | 60.8 |
| PaddleOCR 3 PP-OCRv5 (th) | 81.1 | 90.4 | 82.9 | 93.1 | 55.5 | 75.8 | 41.6 |
| Qwen3.5-9B | 80.1 | 34.5 | 88.2 | 91.8 | 68.5 | 82.0 | 54.1 |
| Tesseract 5 (tha+eng) | 75.4 | 71.7 | 82.3 | 71.3 | 52.2 | 75.0 | 26.4 |
| PaddleOCR-VL 1.6 | 72.4 | 80.8 | 79.7 | 70.3 | 57.6 | 68.2 | 13.4 |
| DeepSeek-OCR-2 | 69.0 | 92.8 | 84.7 | 91.4 | 55.2 | 77.5 | 3.9 |
Bold is the best in each column. The 2.1 row is v2.1.1, as on the model card; the latest version, v2.1.4, averages 88.3 on the 12 sets and 84.1 on ThaiOCRBench. The 12-set printed average covers budget documents, the Royal Gazette, SEA-DocBench, Wikisource old books, Administrative Court judgments, ThaiOCRBench, th-docs-tables and three OCR104 sets; handwriting is not in it. The full table and every engine's speed are on the model card. Court judgments are in-domain: other court documents are in the training data.
How to use it
hf download iapp/OpenThai2.1-OCR-Text-20261118 --local-dir OpenThai2.1-OCR-Text
pip install -r OpenThai2.1-OCR-Text/requirements.txt
cd OpenThai2.1-OCR-Text
from runtime.line_engine import LineOCR

ocr = LineOCR(".", threads=1)
r = ocr.read("page.png")      # path, bytes, ndarray or PIL image
print(r["text"])              # text in reading order (columns one after another)
r["lines"]                    # [{"text", "confidence", "row", "box"}]
For throughput, run one worker process per core with threads=1.
🔁 Using 2.0?
- The old links and model names still work (
iapp/OpenThai2.0-OCR-Markdownandiapp/OpenThai2.0-OCR-Text). Hugging Face redirects them to the new names, and you get 2.1. - To keep the old version, pass
revision="v2.0.0"when you download. - So that an update never changes your output unnoticed, pin
revision="v2.1.0"(OCR Markdown) orrevision="v2.1.4"(OCR Text).
🤔 Why free?
Millions of pages of Thai documents in government offices, hospitals and companies cannot be sent to a foreign cloud. We want every one of them to be able to run OCR on their own machines. And anyone building an AI chatbot on their organisation's documents has to start by reading those documents correctly.
⚠️ Honestly: what it is not good at yet
- Phone photos, English pages and formulas: Typhoon OCR V2 2B is still ahead (MDPBench 87.0, olmOCR-bench 84.7, OmniDocBench 91.5). For the next version the team is collecting real photos of Thai documents and formula data.
- Formulas are still OCR Markdown's weakest part.
- Pictures and figures with no text can still come back with invented text (blank pages are now skipped).
- Chinese is not a target language; it reads noticeably worse than English.
- Full handwritten pages are not a target. OCR Markdown reads handwriting at line level; OCR Text reads print only.
- Short crops of photographed text read worse than full pages: OCR Markdown scores 94.5 on OCR104 document photos.
- Tables unlike Thai government documents can still come out with rows missing or a row span wrong.
- Thai digits occasionally come out as Arabic digits.
- OCR Text: heavily decorative fonts can be misread, loopless fonts can still swap letters (ท for า), stamps come out as text, and the bf16 speed needs a CPU with AMX (Sapphire Rapids or later).
The team is working on it. Thanks to the Typhoon team for raising the bar for Thai OCR with us.
👨👩👧 The OpenThai 2 family
| Model | What it does | Size | Status |
|---|---|---|---|
| OpenThai 2.0 | Thai chat and reasoning LLM that reads images | 27B | Released |
| OpenThai 2.0 Legal | Thai legal model for RAG | 30B-A3B | Released |
| OpenThai-SystemOne | Thai + English decision model (does not generate text) | 0.8B | Released |
| OpenThai 2.1 OCR Markdown | Document pages to Markdown, tables stay tables | 0.63B | Updated 18 Nov |
| OpenThai 2.1 OCR Text | Printed-text OCR on a CPU | 6.6 MB | Updated 18 Nov |
| OpenThai 2.0 ASR Streaming | Live Thai speech to text | 0.64B | Released |
🏷️ Apps built on OpenThai OCR
If your app uses this model, send it in at openthai.ai/powered-by to be listed. The Powered by badge for your app is there too.
🤝 Get involved
- Have a Thai document that no OCR can read (with no personal data in it)? Send it to us to try.
- Talk to us on Discord and in the Facebook group.
📄 Licence and credits
- OpenThai 2.1 OCR Markdown: OpenMDW-1.1, which allows any use, including commercial use. It is a derivative of NVIDIA Nemotron 3.5 Parse, also OpenMDW-1.1; the tokenizer is MIT-licensed, and our llama.cpp fork is MIT-licensed, as llama.cpp is. Built on NVIDIA Nemotron.
- OpenThai 2.1 OCR Text: Apache-2.0. The detector and the recognizer's starting point are PaddlePaddle's PP-OCRv6-tiny (Apache-2.0).
Developed by iApp, launched with AIEAT.
🙏 Thank you, Siam AI
Both models were trained on NVIDIA H100 GPUs supported by Siam AI Corporation. Our sincere thanks for their continued support of open Thai AI, and thanks to NVIDIA for Nemotron 3.5 Parse.