📄 We did it! Thai document AI, two models, free
Announced 12 November 2026
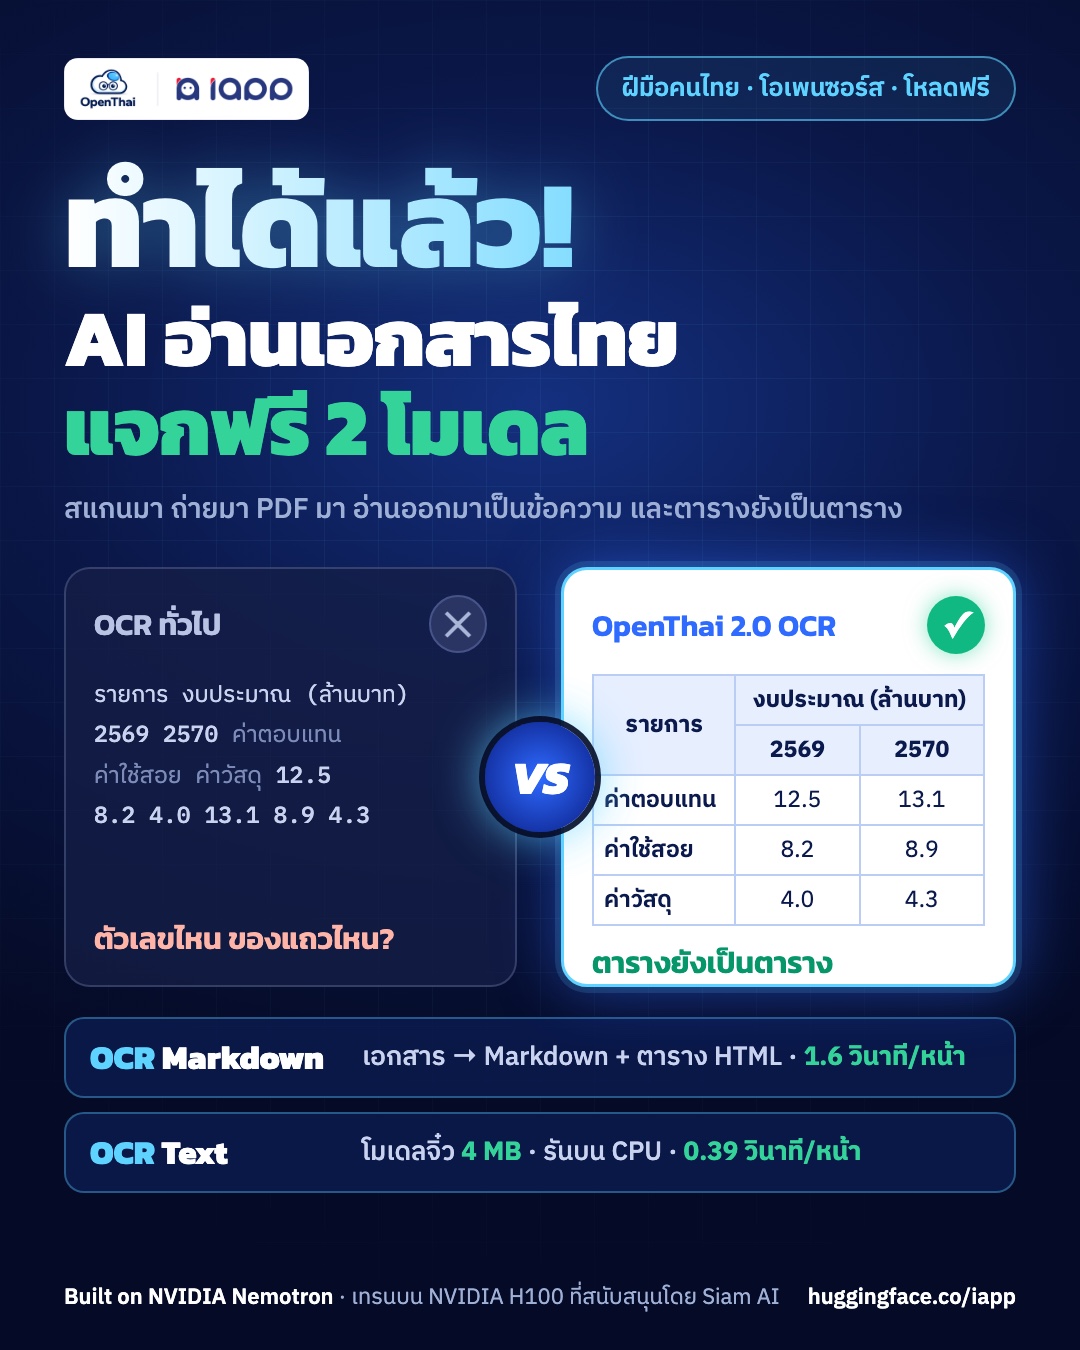
OCR Markdown 0.63BOCR Text 4 MBCommercial use allowedThai + Englishv1.0.0
Sound familiar? You scan a stack of government documents and want the text, but the OCR reads every table as one long line. You can no longer tell which number belongs to which row, so you end up retyping it cell by cell.
Today the OpenThai team at iApp Technology releases two Thai OCR models that anyone can download and use for free, commercial use included.
| OpenThai 2.0 OCR Markdown | OpenThai 2.0 OCR Text | |
|---|---|---|
| What it does | Page → Markdown, tables as HTML (merged cells included), with a box and a class for every block | Page → text in reading order, with a box and a confidence for every line |
| Size | 0.63B parameters | 1.02M parameters, 4.2 MB of ONNX |
| Runs on | One NVIDIA GPU, served with vLLM | CPU only, no GPU needed |
| Speed | 1.6 s per page on one H100 | 0.39 s per page; about 950 pages a minute on 8 cores |
| Built from | NVIDIA Nemotron 3.5 Parse | PaddlePaddle PP-OCRv6-tiny |
| Licence | OpenMDW-1.1 | Apache-2.0 |
| Best for | Pages with tables, budgets, the Royal Gazette, preparing documents for RAG | Plain text at volume, machines without a GPU, confidential documents that cannot leave the building |
1) OpenThai 2.0 OCR Markdown: tables stay tables
It reads a Thai document page into Markdown, with tables as HTML including rowspan and colspan. It is a full fine-tune of NVIDIA Nemotron 3.5 Parse (0.63B), so it keeps Parse's layout boxes, block classes and reading order, and runs anywhere Parse runs.
- 95.2 on 65 real Thai government and university pages with tables (th-docs-tables v1), against 91.6 for Typhoon OCR V2 2B (+3.6, 95% interval [+1.2, +6.2]).
- 98.7% character accuracy on 339 Royal Gazette pages published after training finished (4–9 November 2026). Typhoon OCR V2 2B: 94.6.
- 90.3 average over 12 printed Thai text sets, the highest of the 15 engines we tested. Typhoon OCR V2 2B scores 89.6, a difference that is not significant.
- 1.6 s per page on one NVIDIA H100 (median of 12 table pages, one page at a time).
- No repetition loops on any test page, nor on 6,137 development pages.
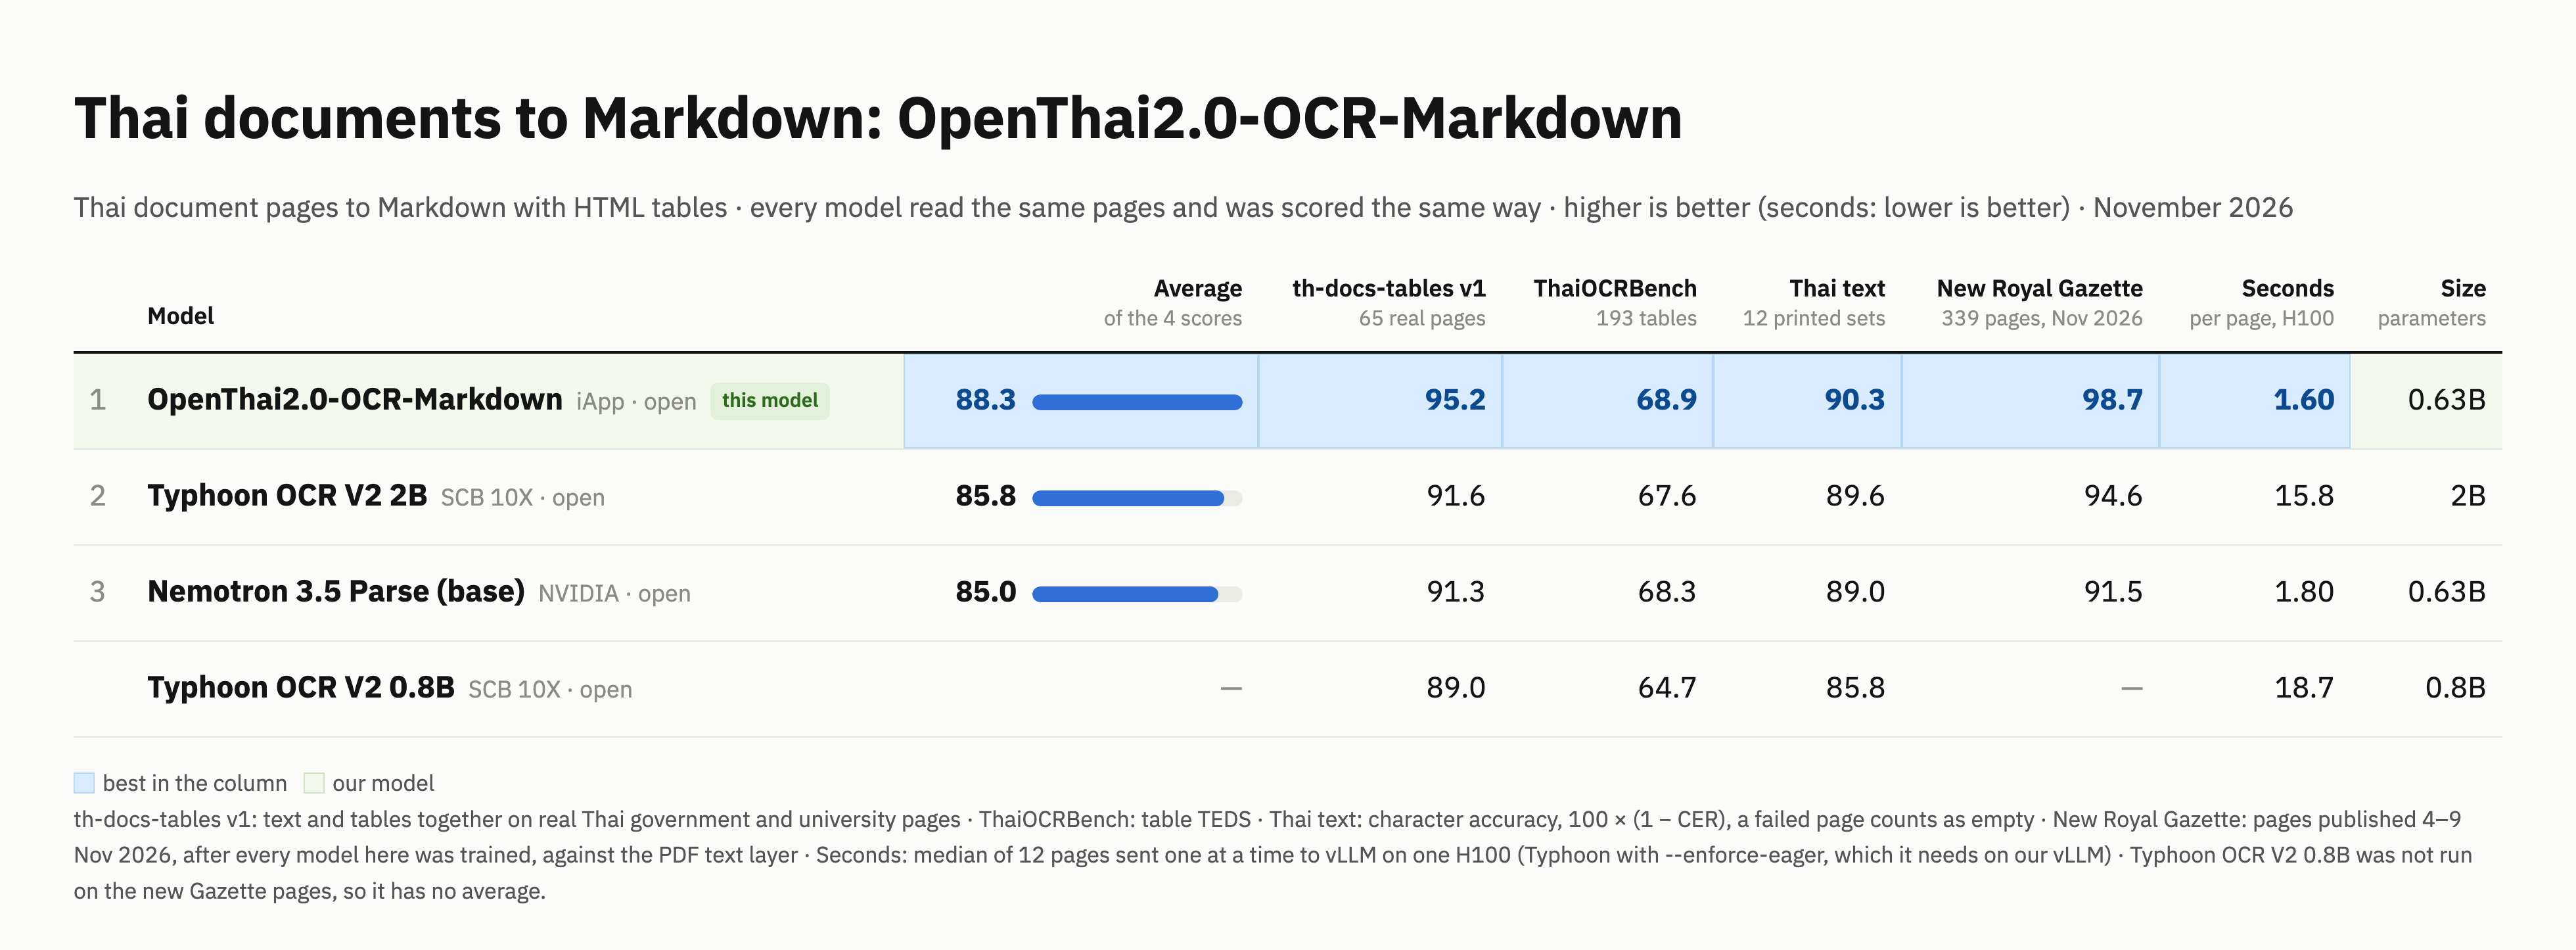
| Model | Size | th-docs-tables v1 (65 pages) | ThaiOCRBench tables (193 images) | Thai text, printed (12 sets) | New Royal Gazette pages (339) | Average | Seconds per page |
|---|---|---|---|---|---|---|---|
| OpenThai2.0-OCR-Markdown | 0.63B | 95.2 | 68.9 | 90.3 | 98.7 | 88.3 | 1.6 |
| Nemotron 3.5 Parse (base) | 0.63B | 91.3 | 68.3 | 89.0 | 91.5 | 85.0 | 1.8 |
| Typhoon OCR V2 2B | 2B | 91.6 | 67.6 | 89.6 | 94.6 | 85.8 | 15.8 |
| Typhoon OCR V2 0.8B | 0.8B | 89.0 | 64.7 | 85.8 | — | — | 18.7 |
Bold marks the best in each column. Average is the mean of the four accuracy columns. On ThaiOCRBench tables (+1.3) and printed text (+0.76) the difference from Typhoon OCR V2 2B is not significant. Typhoon ran with --enforce-eager, which its model needs on our vLLM version; with CUDA graphs it would be faster. The new Gazette pages are documents of a kind the model knows (its training data has Gazette pages from earlier months), but none of these pages was trained on.
Use
Serve it with vLLM exactly like the base model, then read pages with NVIDIA's DocumentParser (box-and-class prompt, single pass):
vllm serve iapp/OpenThai2.0-OCR-Markdown --served-model-name nemotron-parse --trust-remote-code
from nemotron_parse.inference import DocumentParser, GenerationError

with DocumentParser(base_url="http://localhost:8000/v1", model="nemotron-parse") as parser:
    doc = parser.parse("page.png", mode="single")
    print(doc["markdown"])  # Markdown; tables as HTML with rowspan/colspan
Use box mode, the mode we tested. Full setup is in the model card.
2) OpenThai 2.0 OCR Text: 4 MB, no GPU
Thai and English printed-text OCR on an ordinary CPU: a PP-OCRv6-tiny line detector (1.8 MB) and a Thai line recognizer trained by iApp (2.4 MB), run with OpenVINO or ONNX Runtime.
- 0.39 s per dense A4 page, about 950 pages a minute on 8 Xeon cores, about 450 MB of RAM per worker.
- Works offline. Confidential documents never leave the machine.
- 99.5 on budget documents and 96.3 on the Royal Gazette (Gemini 2.5 Flash 81.0 and 92.6; Google Cloud Vision 75.0 and 87.8).
- Turns pages upright, deskews, reads multi-column pages in order and reads light-on-dark text. It passes all 22 conditions of our robustness suite.
- iApp's OpenThai 2.0 OCR Text API is built on this model.
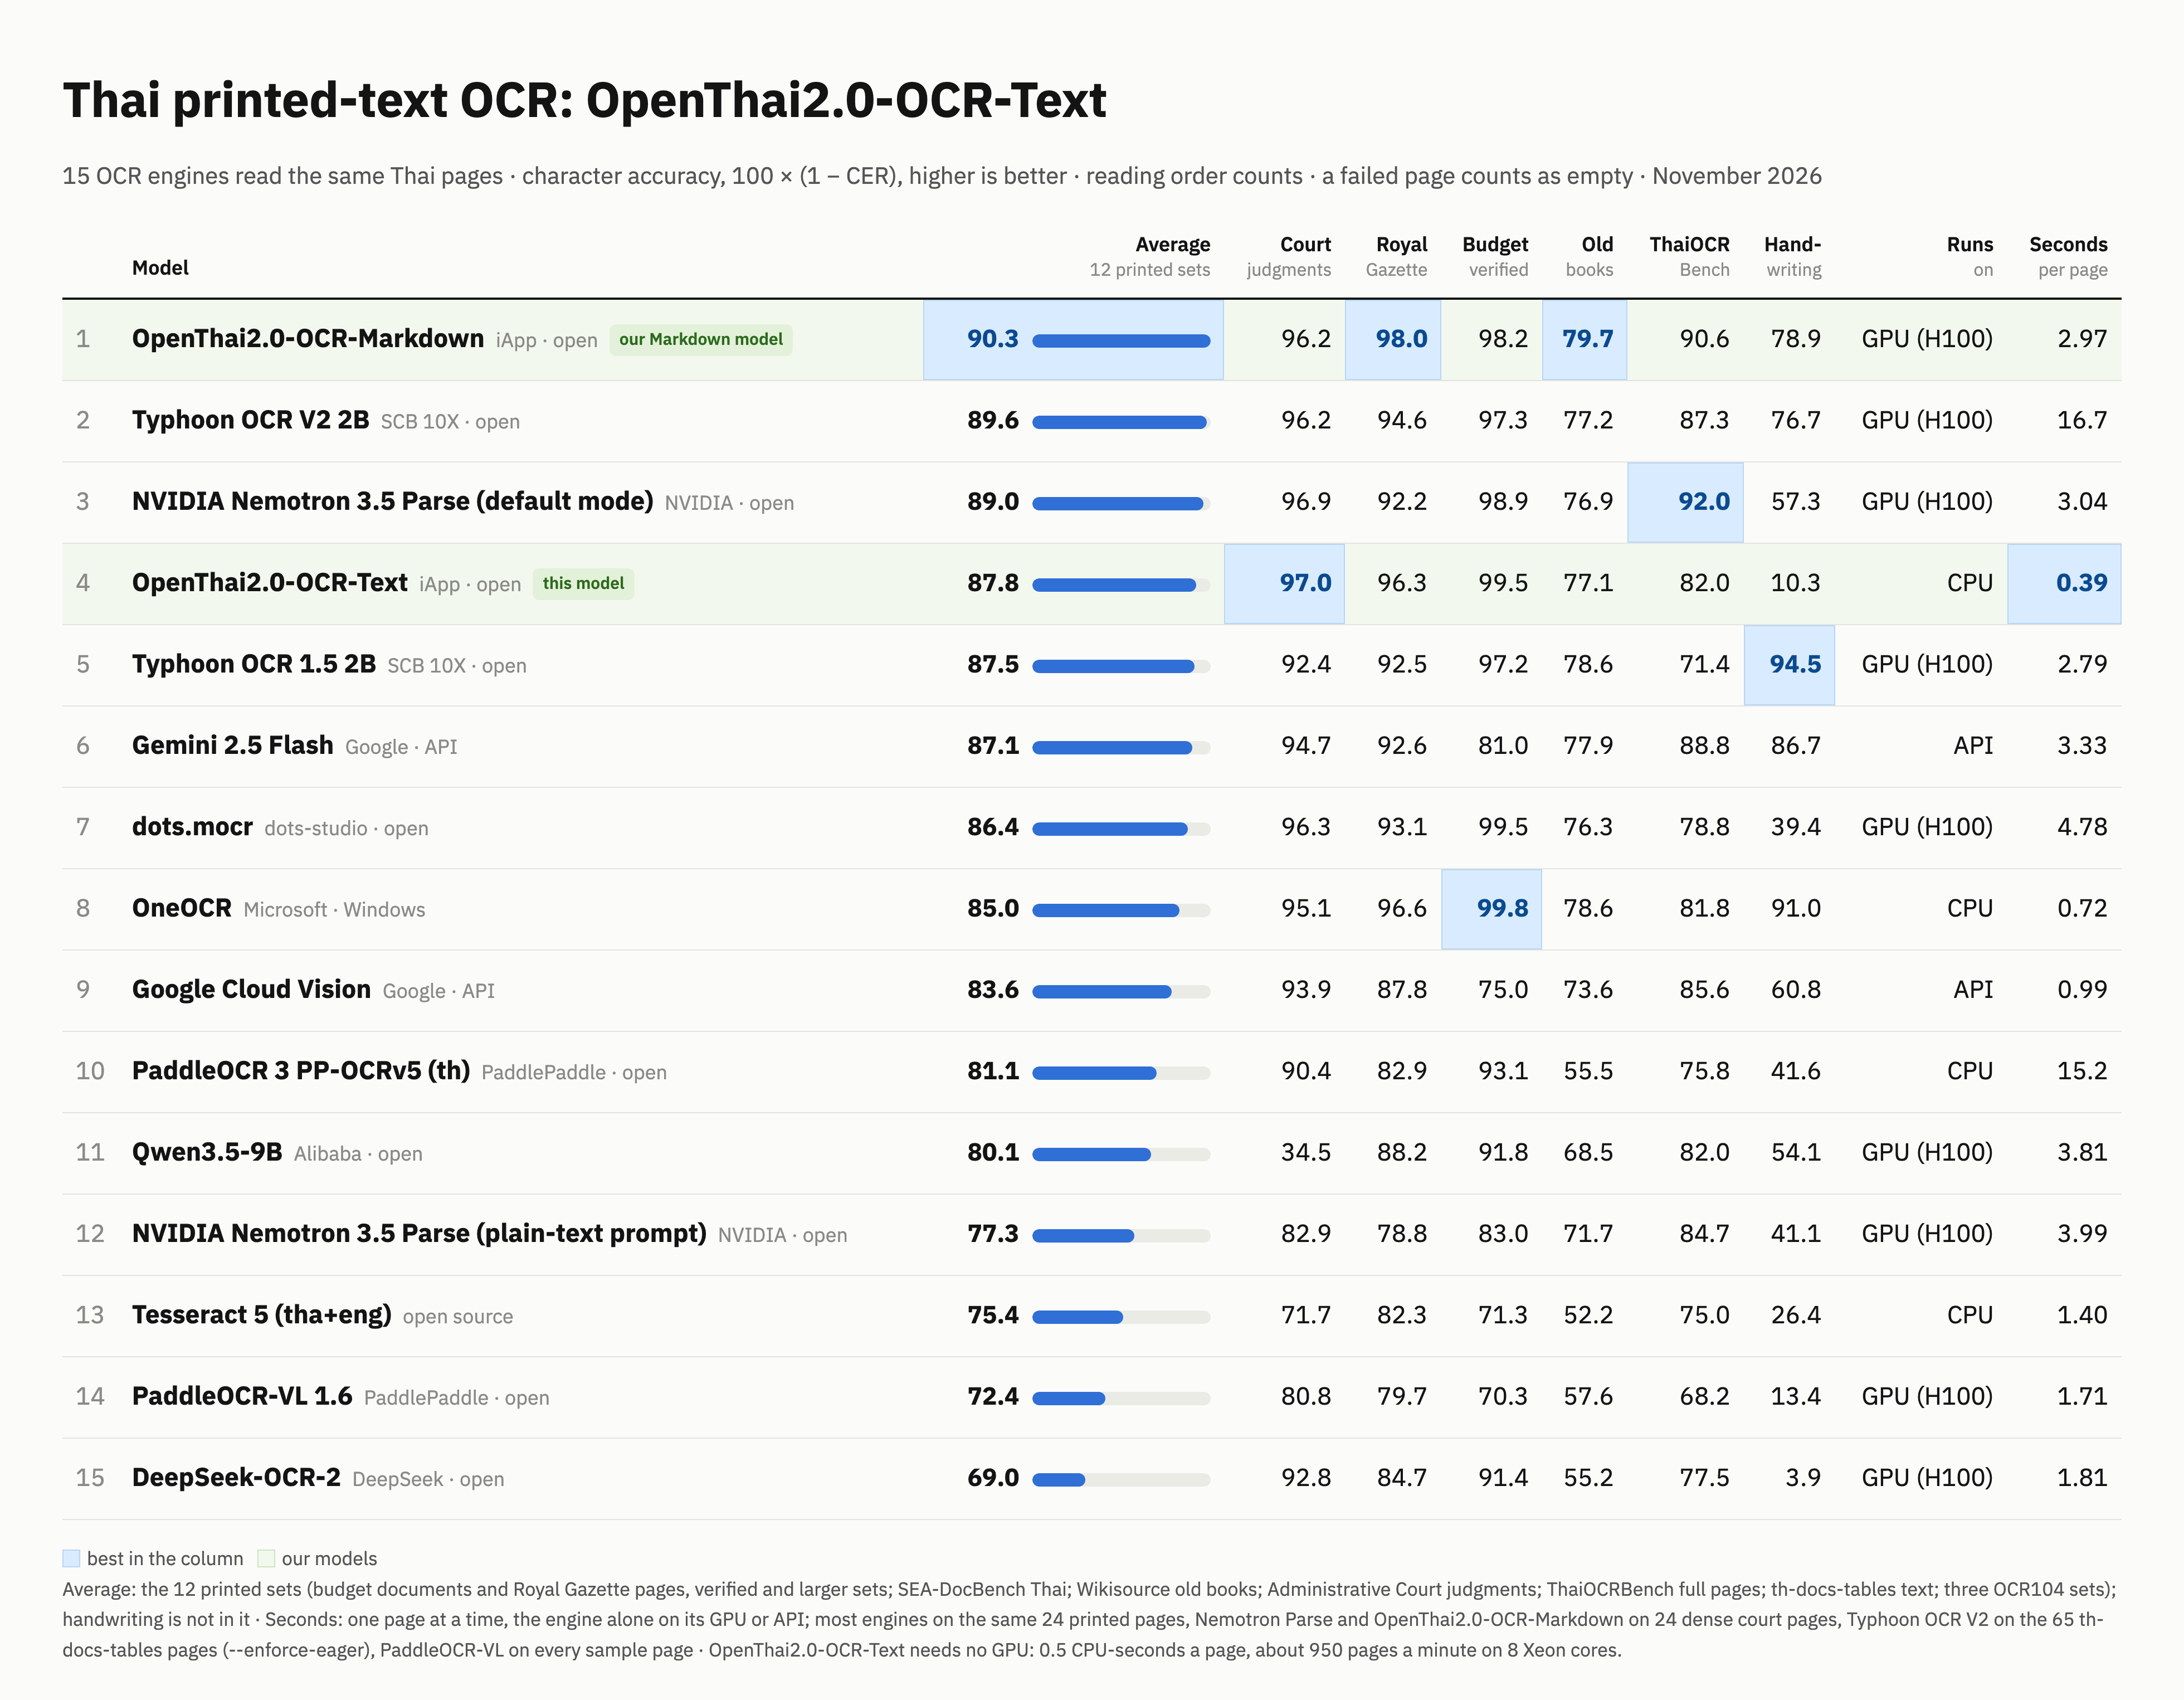
Every engine read the same pages and was scored the same way: character accuracy, 100 × (1 − CER), higher is better.
| Engine | Average, 12 printed sets | Court judgments | Royal Gazette | Budget | Old books | ThaiOCRBench | Handwriting |
|---|---|---|---|---|---|---|---|
| OpenThai2.0-OCR-Text (this model, CPU) | 87.8 | 97.0 | 96.3 | 99.5 | 77.1 | 82.0 | 10.3 |
| OpenThai2.0-OCR-Markdown (GPU) | 90.3 | 96.2 | 98.0 | 98.2 | 79.7 | 90.6 | 78.9 |
| Typhoon OCR V2 2B | 89.6 | 96.2 | 94.6 | 97.3 | 77.2 | 87.3 | 76.7 |
| NVIDIA Nemotron 3.5 Parse | 89.0 | 96.9 | 92.2 | 98.9 | 76.9 | 92.0 | 57.3 |
| Typhoon OCR 1.5 2B | 87.5 | 92.4 | 92.5 | 97.2 | 78.6 | 71.4 | 94.5 |
| Gemini 2.5 Flash | 87.1 | 94.7 | 92.6 | 81.0 | 77.9 | 88.8 | 86.7 |
| dots.mocr | 86.4 | 96.3 | 93.1 | 99.5 | 76.3 | 78.8 | 39.4 |
| OneOCR (Microsoft, Windows) | 85.0 | 95.1 | 96.6 | 99.8 | 78.6 | 81.8 | 91.0 |
| Google Cloud Vision | 83.6 | 93.9 | 87.8 | 75.0 | 73.6 | 85.6 | 60.8 |
| PaddleOCR 3 PP-OCRv5 (th) | 81.1 | 90.4 | 82.9 | 93.1 | 55.5 | 75.8 | 41.6 |
| Qwen3.5-9B | 80.1 | 34.5 | 88.2 | 91.8 | 68.5 | 82.0 | 54.1 |
| Tesseract 5 (tha+eng) | 75.4 | 71.7 | 82.3 | 71.3 | 52.2 | 75.0 | 26.4 |
| PaddleOCR-VL 1.6 | 72.4 | 80.8 | 79.7 | 70.3 | 57.6 | 68.2 | 13.4 |
| DeepSeek-OCR-2 | 69.0 | 92.8 | 84.7 | 91.4 | 55.2 | 77.5 | 3.9 |
Bold marks the best in each column. The average covers 12 printed sets (budget, Royal Gazette, SEA-DocBench, Wikisource old books, Administrative Court judgments, ThaiOCRBench, th-docs-tables and three OCR104 sets); handwriting is not in it. The full table, with Nemotron 3.5 Parse's plain-text prompt and every engine's speed, is in the model card. Court judgments are in-domain: court scans (other documents than the ones tested) are in the training data.
Use
hf download iapp/OpenThai2.0-OCR-Text --local-dir OpenThai2.0-OCR-Text
pip install openvino opencv-python-headless pyclipper numpy
cd OpenThai2.0-OCR-Text
from runtime.line_engine import LineOCR

ocr = LineOCR(".", threads=1)
r = ocr.read("page.png")      # path, bytes, ndarray or PIL image
print(r["text"])              # text in reading order
r["lines"]                    # [{"text", "confidence", "row", "box"}]
For throughput, run one worker process per core with threads=1.
🤔 Why give it away
Millions of Thai pages in government offices, hospitals and companies cannot be sent to a foreign cloud. We want every one of them to be readable on the organisation's own machines. And anyone building an AI chatbot on their own documents has to start by reading those documents correctly.
⚠️ Honestly: what it is not good at yet
- Fully handwritten pages are not a target. OCR Markdown reads handwriting at line level; OCR Text reads printed text only.
- Photographed single words and very short crops read worse than full pages: OCR Markdown scores 96.4 on OCR104 document photos, against 99.8 for Typhoon OCR V2 2B.
- Tables unlike Thai government documents are read about as well as by the base model (ThaiOCRBench tables 68.9, base 68.3). Some still come out with missing rows or a wrong row span.
- Thai digits occasionally come out as Arabic digits (112 out of about 22,000 Thai digits on the 339 Gazette pages).
- Dot-matrix print (bank passbooks): 89% on generated development crops; we have no real test set yet.
- Vertical text, such as rotated table headers, can be misread.
- OCR Text: heavily decorative fonts can be misread, stamps come out as text, and the bf16 speed needs a CPU with AMX (Sapphire Rapids or later).
The team is working on these. Thanks also to the Typhoon team for raising the bar for Thai OCR with us.
👨👩👧 The OpenThai 2.0 family
| Model | What it does | Size | Status |
|---|---|---|---|
| OpenThai 2.0 | Thai chat and reasoning LLM, reads images | 27B | Released |
| OpenThai 2.0 Legal | Thai legal model for RAG | 30B-A3B | Released |
| OpenThai-SystemOne | Thai + English decision model (no text generation) | 0.8B | Released |
| OpenThai 2.0 OCR Markdown | Page → Markdown, tables stay tables | 0.63B | Released |
| OpenThai 2.0 OCR Text | Printed-text OCR on a CPU | 4 MB | Released |
🤝 Contribute
- Have a Thai document that no OCR can read (with no personal data in it)? Send it to us and we will try it.
- Talk to us on the OpenThaiGPT Discord and in the Facebook group.
📄 Licence and credits
- OpenThai 2.0 OCR Markdown: OpenMDW-1.1, which allows use without restriction, commercial use included. It is a derivative of NVIDIA Nemotron 3.5 Parse (also OpenMDW-1.1); the tokenizer is MIT-licensed. Built on NVIDIA Nemotron.
- OpenThai 2.0 OCR Text: Apache-2.0. The detector and the recognizer's starting point are PaddlePaddle's PP-OCRv6-tiny (Apache-2.0).
Developed by iApp Technology / the OpenThai team.
🙏 Thanks to Siam AI
Both models were trained on NVIDIA H100 GPUs provided by Siam AI Corporation. Our sincere thanks for their continued support of open Thai AI, and thanks to NVIDIA for Nemotron 3.5 Parse.