🎙️ We did it! Live Thai speech to text, free to download
Announced 13 November 2026
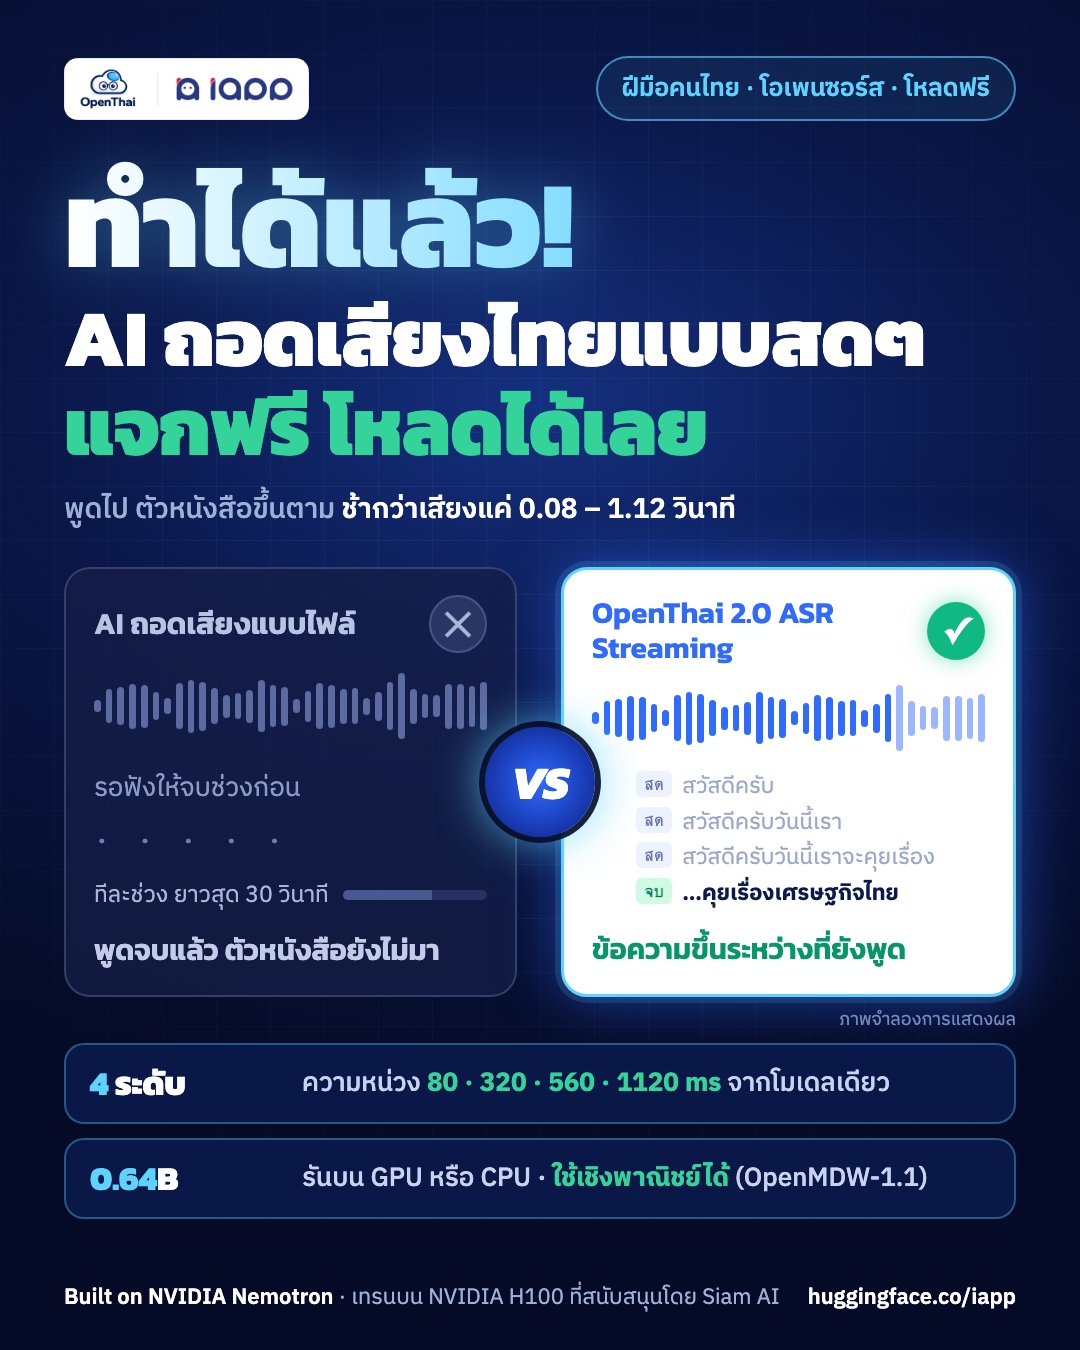
0.64B80–1120 ms behind the voiceGPU or CPUCommercial use allowedOpenMDW-1.1
Sound familiar? You are watching a live stream, sitting in a class or in an online meeting, and you want live Thai captions. But most open Thai speech-to-text models have to hear a whole chunk before they write anything, and by the time the text appears the speaker has moved on.
Today the OpenThai team at iApp Technology releases OpenThai 2.0 ASR Streaming, free to download: a Thai speech-to-text model that writes while people are still talking. Commercial use is allowed.
| OpenThai 2.0 ASR Streaming | |
|---|---|
| What it does | Live Thai speech to text, 80 to 1120 ms behind the voice |
| Latency | One model, four settings: 80, 320, 560 and 1120 ms |
| Size | 0.64B parameters |
| Built on | NVIDIA Nemotron 3.5 ASR Streaming 0.6B |
| On a GPU | One NVIDIA H100 keeps up with about 20 live streams (at 560 ms) and transcribes files about 257x faster than real time |
| On a CPU | 8 threads keep up with one live stream at 320 or 560 ms (not at 80 ms), transcribe files at about 4x real time, and need about 6.5 GB of RAM |
| Files | Weights on Hugging Face, plus an ONNX export (full precision and int8) |
| Licence | OpenMDW-1.1, commercial use allowed |
Highlights
- Text while you speak. The text arrives 0.08 to 1.12 seconds behind the voice. One model has four settings (80, 320, 560 and 1120 ms): pick speed or accuracy.
- Many streams on one GPU. One NVIDIA H100 keeps up with about 20 live streams at 560 ms and transcribes files about 257x faster than real time.
- No GPU needed. A CPU with 8 threads keeps up with one live stream at 320 or 560 ms, with about 6.5 GB of RAM.
- Runs on your own machines. Audio never leaves the organisation, which suits organisations that cannot send audio to a foreign cloud, such as hospitals and banks.
- The model behind OpenThai ASR Realtime, iApp's live speech-to-text WebSocket API.
ONNX export: full precision and int8huggingface.co/iapp/OpenThai2.0-ASR-Streaming-ONNX
Results
We compared it with Typhoon ASR Streaming 0.6B, which is built on the same NVIDIA base. We decoded both ourselves, on the same test sets, with the same script, at 560 ms.
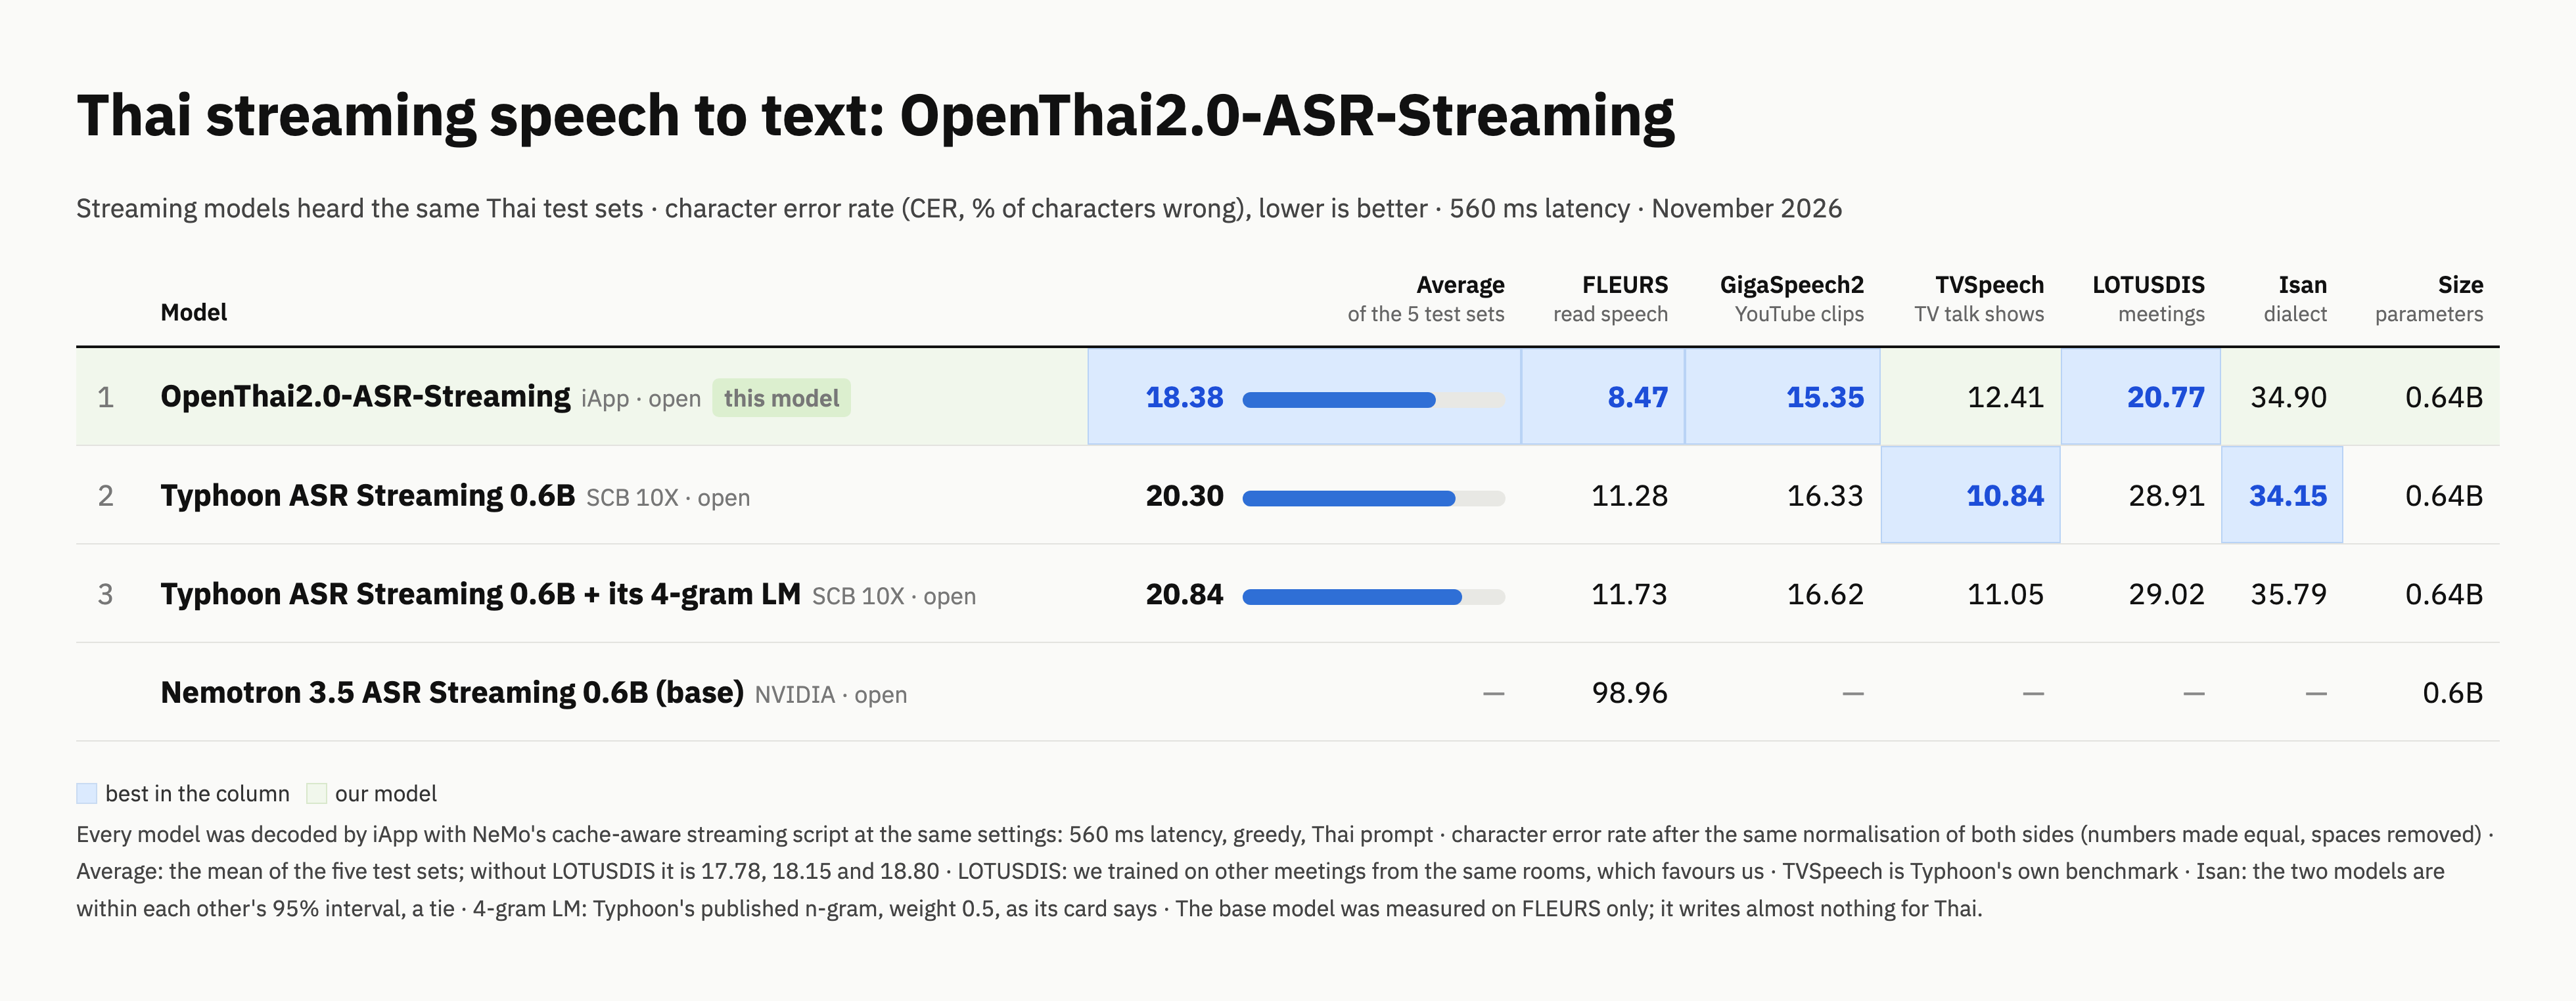
| Test set | Speech | OpenThai 2.0 ASR Streaming | Typhoon ASR Streaming 0.6B | Result |
|---|---|---|---|---|
| FLEURS | Read speech | 8.47 | 11.28 | We lead |
| GigaSpeech2 | YouTube clips | 15.35 | 16.33 | We lead |
| LOTUSDIS | Meetings | 20.77 | 28.91 | We lead (favours us, see note) |
| TVSpeech | TV talk shows | 12.41 | 10.84 | Typhoon leads |
| Isan | Isan dialect | 34.90 | 34.15 | Tie |
Numbers are the % of characters wrong; lower is better. Bold is the better of the two. LOTUSDIS: we trained on other meetings recorded in the same rooms, so this set favours us. Isan: the gap is small enough to count as a tie.
From 99% to 8.47%
- Before fine-tuning, the NVIDIA base model, Nemotron 3.5 ASR Streaming 0.6B, got 98.96% of characters wrong on FLEURS Thai. It now gets 8.47% wrong on the same test set.
- We added 1,901 Thai pieces to the tokenizer.
- Training used 12,373 hours of Thai speech and 961 hours of English.
- Trained on NVIDIA H100 GPUs supported by Siam AI.
How to use it
hf download iapp/OpenThai2.0-ASR-Streaming --local-dir OpenThai2.0-ASR-Streaming
How to run it, how to set the latency, and the included server for files and live audio are in the model card.
- Cut long recordings at pauses before decoding. The included server does this for you. Decoding one long recording as a single stream drops words after quiet pauses.
- English words: the default
th-THmode writes everything in Thai script;th-mixwrites only some English words in Latin letters.
Rather not run a GPU? OpenThai ASR Realtime serves the same model as a WebSocket API. It is free during the launch, not forever.
🤔 Why free?
We want people who are deaf or hard of hearing, and older people, to be able to follow live streams, the news, classes and meetings with live Thai captions, anywhere. And anyone building a Thai voice assistant that responds quickly has to start by keeping up with Thai speech.
⚠️ Honestly: what it is not good at yet
- TV talk shows: Typhoon still does better (TVSpeech 12.41 vs 10.84).
- Isan dialect: a tie with Typhoon (34.90 vs 34.15).
- English words: the default mode writes them all in Thai script;
th-mixwrites only some of them in Latin letters. - Long recordings must be cut at pauses before decoding (the included server and iApp's hosted service already do this).
- On a CPU it keeps up live at 320 and 560 ms only, not at 80 ms.
The team is working on it. Thanks to the Typhoon team for raising the bar for Thai speech recognition with us.
👨👩👧 The OpenThai 2.0 family
| Model | What it does | Size | Status |
|---|---|---|---|
| OpenThai 2.0 | Thai chat and reasoning LLM that reads images | 27B | Released |
| OpenThai 2.0 Legal | Thai legal model for RAG | 30B-A3B | Released |
| OpenThai-SystemOne | Thai + English decision model (does not generate text) | 0.8B | Released |
| OpenThai 2.0 OCR Markdown | Document pages to Markdown, tables stay tables | 0.63B | Released |
| OpenThai 2.0 OCR Text | Printed-text OCR on a CPU | 4 MB | Released |
| OpenThai 2.0 ASR Streaming | Live Thai speech to text | 0.64B | Released |
🤝 Get involved
- Planning live captions for an event, or found audio it gets badly wrong (with no personal data in it)? Tell the team.
- Talk to us on Discord and in the Facebook group.
- More on the iApp site: the launch post and the model page.
📄 Licence and credits
- OpenThai 2.0 ASR Streaming: OpenMDW-1.1, commercial use allowed. A derivative of NVIDIA Nemotron 3.5 ASR Streaming 0.6B. Built on NVIDIA Nemotron.
Developed by iApp Technology / the OpenThai team.
🙏 Thank you, Siam AI
This model was trained on NVIDIA H100 GPUs supported by Siam AI Corporation. Our sincere thanks for their continued support of open Thai AI, and thanks to NVIDIA for Nemotron 3.5 ASR Streaming.