Upgraded! OpenThai 2.1 OCR now reads phone photos of documents, better because of real users
Upgraded! OpenThai 2.1 OCR now reads phone photos of documents, writes formulas as LaTeX, and the tiny model that runs on a CPU got better from real users' feedback. Still free, and commercial use is allowed.
Six days ago we released OpenThai 2.0 OCR, and a lot of people put it to real use: a website that reads documents in the browser, apps for Windows, and tests on almost a thousand pages of government documents. The team fixed every problem raised in the comments. Here is what is better in version 2.1.
1) OpenThai 2.1 OCR Markdown (document pages to Markdown, tables stay tables)
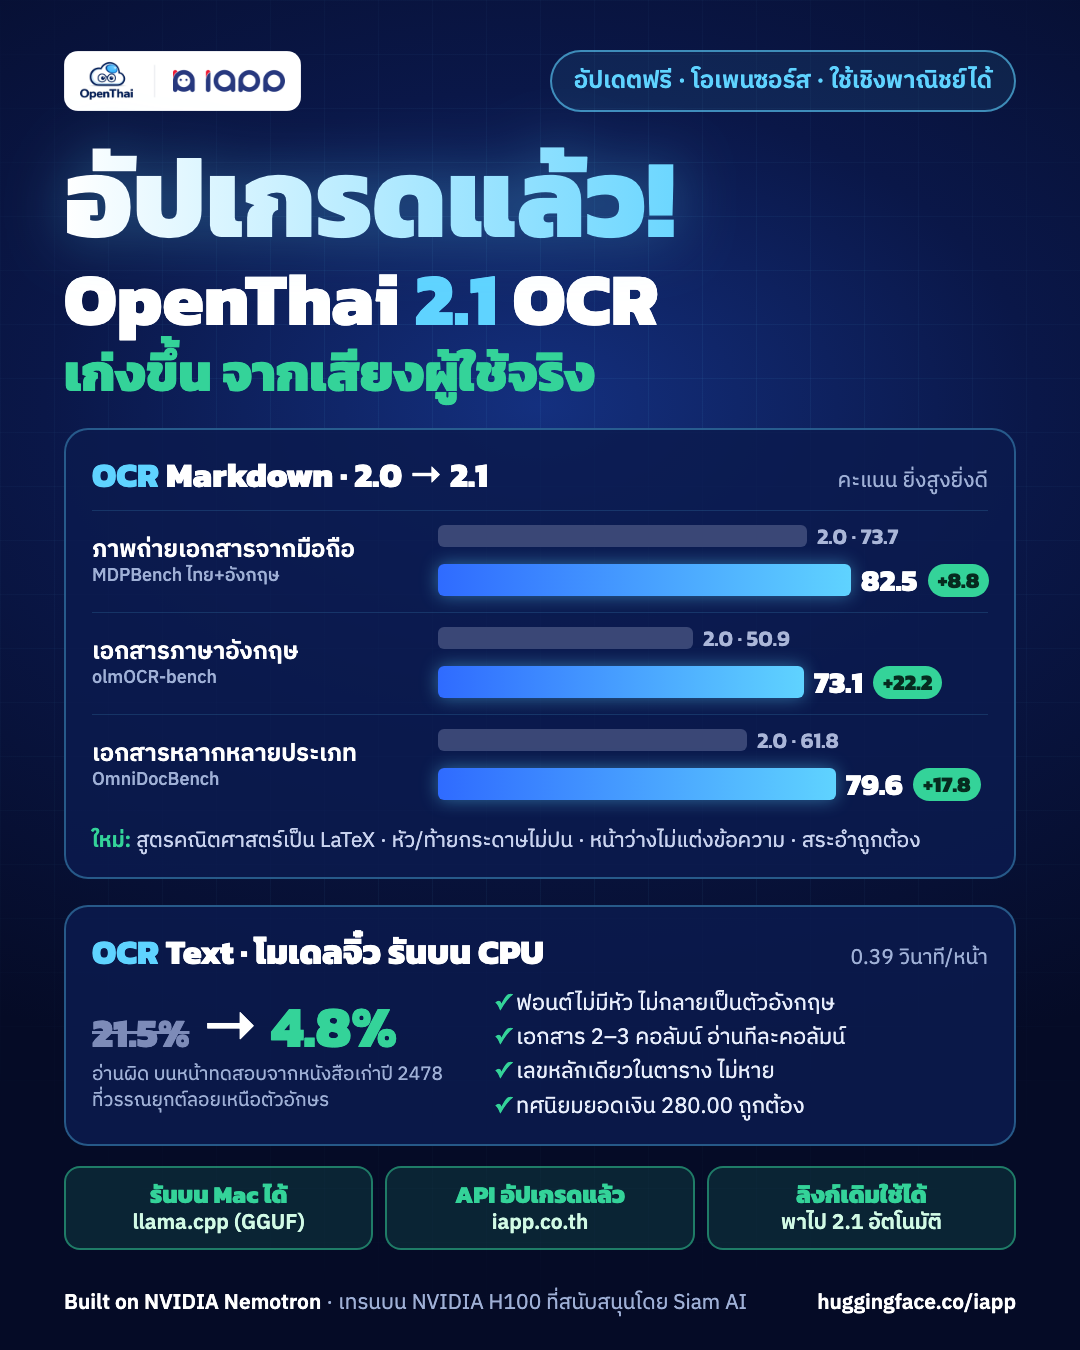
- Phone photos of documents (MDPBench, Thai and English): 73.7 to 82.5
- Thai only: 72.7 to 80.7
- English documents (olmOCR-bench): 50.9 to 73.1
- OmniDocBench: 61.8 to 79.6
- More kinds of page: academic papers, books, comics, exams, magazines, newspapers, reports, slides and textbooks
- Formulas come out as LaTeX, page headers and footers stay out of the text, blank pages no longer get invented text, and ำ is written correctly
- Thai government tables are as accurate as before (94.0, ahead of Typhoon OCR V2 2B at 91.6)
- The same size, 0.63B, and the same speed, 1.5 s per page on an H100
- New: runs on a Mac with llama.cpp (GGUF), about 6 s per page on an M3 Max, no vLLM needed
2) OpenThai 2.1 OCR Text (a tiny 6.6 MB model that runs on a CPU)
- Old books with floating tone marks: on a test page from a 1935 book, errors fell from 21.5% to 4.8%
- Loopless fonts (Kanit, Prompt, Sukhumvit Set) no longer turn into Latin letters
- Two- and three-column pages are read column by column, without mixing
- A single digit in a table cell (a quantity of 2), day codes such as M T W, and decimals in amounts are no longer lost or garbled
- Less memory on Mac and Windows
- The same speed: 0.39 s per page, no GPU, no internet connection
Honestly: on phone photos, English pages and formulas, Typhoon OCR V2 2B is still ahead of us (MDPBench 87.0). For the next version the team is collecting real photos of Thai documents.
Thank you to everyone who tried it and sent feedback, in the comments and on GitHub. Every fix in this version came from real users.
Using 2.0? The old links still work and take you to the new version automatically. To keep the old 2.0, pass revision="v2.0.0" when you download.
Download: huggingface.co/iapp/OpenThai2.1-OCR-Markdown-20261118 and huggingface.co/iapp/OpenThai2.1-OCR-Text-20261118 GGUF for Mac and CPU: huggingface.co/iapp/OpenThai2.1-OCR-Markdown-20261118-GGUF Rather not run a GPU? The API is already on 2.1, at 0.15 IC per page: iapp.co.th/docs/ocr/document-markdown Full results, usage and limits: OpenThai 2.1 OCR model page
Built on NVIDIA Nemotron · Trained on NVIDIA H100 GPUs supported by Siam AI